Apache Spark WTF??? — 🪲 Debuggin’ 🦗
In the world of Big Data, our heap isn’t just memory — it’s a tectonic plate shifting under the weight of a million shuffle partitions…
“Put your logs and traces on, baby
’Cause I’m debuggin’
I’m debuggin’, debuggin’ with Semeru
Just trying to figure it out, maybe”
(adapted from “Beggin’” by Måneskin)
🌋 Java Volcano Alert: IBM Semeru is Erupting!
Hold onto your lab coats — IBM Semeru is the Java volcano that behaves… mostly. Calm on the surface, but under the hood, it’s a perfectly engineered magma chamber of performance, efficiency, and debugging sanity. Let’s walk through the lava flows …
Lava Flow #1: Fast & Lean Magma
OpenJ9 JVM is the lava-fueled core of Semeru. It starts fast, sips memory politely, and handles garbage collection like a seasoned volcanologist controlling lava flows.
Lava Alert: Startup in seconds, not minutes. Memory usage is 20–40% lower than HotSpot (or so they say). GC doesn’t randomly spew lava all over your heap.
Lava Flow #2: Cloud-Ready Eruption
Semeru is tiny enough to fit into your Docker containers without blowing up the image size. It runs on Linux, Windows, and macOS, and slides seamlessly into Kubernetes or serverless workflows.
Lava Alert: Cloud deployments are smooth — no unexpected explosions. Your containers feel like lava tubes, flowing efficiently from node to node.
Lava Flow #3: Debug Without Getting Burned
Debugging Java can feel like poking at an active volcano with a toothpick. Semeru helps you see the magma before it hits:
- Rapid start–stop cycles for fast iteration
- Predictable memory footprint, so your heap doesn’t erupt randomly
- Transparent runtime metrics for safer profiling
Lava Alert: You get insight, control, and fewer “why is everything on fire?” moments.
Lava Flow #4: Certified & Supported Heat
Semeru builds are part of the Eclipse Adoptium ecosystem, with rigorous testing pipelines and optional IBM support. Security patches, performance updates, and enterprise-grade assistance keep your volcano active, but under control.
Lava Alert: Enterprise-ready, TCK-tested (Certified Edition), and backed by a community that knows how to handle molten code.
Lava Flow #5: Fully Compatible OpenJDK
It’s Java, so your existing apps just work. Passes all Java SE compatibility tests. No surprises. We can grab the Semeru Runtime 17 — OpenJDK bundled with IBM’s very nice and very useful OpenJ9 JVM — from here.
Lava Alert: You can ride the lava flow without worrying about unexpected eruptions in production.
🔥 Lava Lab — Xtrace
If IBM Semeru is a volcano, ‑Xtrace is our high-tech lava scanner. It doesn’t just peek at the surface — it dives into the magma chamber, exposing threads, methods, and JVM guts. And because it’s built into the JVM, not layered on like logging or agents, it barely touches performance: no bytecode weaving, no hooks, no constant formatting — just lightweight event taps in the engine itself.
The JVM is split into traceable components:
- j9mm — Memory and GC events
- j9jit — JIT compilation choices
- j9thr — Threads, mutexes, synchronization
- j9vm — Core VM ops like class loading
- j9mt — Method tracing, with wildcards and triggers for selective events
The Trigger Engine is like a smart volcanologist: it reacts only when something’s about to erupt. Set triggers on method calls, exceptions, or lifecycle events, and the JVM can dump, pause, or resume tracing — or even freeze threads to probe timing issues.
Running test_1.py
Here you can find the repo. This script creates a Spark session and an initially empty DataFrame, then loops 25 times, each time adding a new null column, filtering on non-null values (which keeps it empty), and calling explain() to print the query plan and show() to display the DataFrame.
As we saw in I Love It When A Plan Comes Together (Part III), Spark AQE generated a huge plan, spammed TreeNode.generateTreeString thousands of times, and blew up with an OutOfMemory error.
Now, we can trace the calls to this method using:
-Xtrace:methods={org/apache/spark/sql/catalyst/trees/TreeNode.generateTreeString},print=mtmethods={...}– Specifies one or more methods or classes to trace; use JVM internal names (slashes/instead of dots.). Multiple entries can be listed, separated by commas.print=mt– Defines the output format for each traced call.mt= method trace. It tells the JVM to trace method-level events, typically entries and/or exits of the specified methods.
But when we run the test… WTF??? Not only does it stop throwing OOM, it now fires “only” 3,950 calls. Fixed in the latest Spark, maybe? Nope — it was already fixed in Spark 4.0.0. And in Spark 3.5.7? Nope — it still crashes the driver.
So what changed? In Spark 4, TreeNode now lazily initializes metadata like tags and ineffectiveRules only when needed. Memory-leaking Streams became LazyLists, and child lookups now use IdentityHashMap to skip expensive recursive hashCode calls. The result? The driver’s memory footprint drops dramatically, letting Spark handle massive plans that used to crash the system.

3,950 method entries (> lines) and 3,950 exits (< lines).
NOTE: I’m pretty sure I tested this on Spark 4 when analyzing the issue and it failed — but maybe it was a preview build?
Running test_2.py
As we saw in Looks Like An Exception, reading CSV files in Spark internally throws errors com.univocity.parsers.common.input.EOFException , one per row (header of the CSV file included).
Wouldn’t be amazing if we could detect these exceptions without having to get our hands dirty and debug inside the Spark and Univocity code? ‑Xtrace once more to the rescue!
-Xtrace:methods={java/lang/Throwable.<init>},print=mtUnfortunately, even though java/lang/Throwable.<init> allows us to trace the times an object of the Throwable class is instantiated, this will not tell us the exact exception being thrown. For that, we can use another very useful feature of -Xtrace: printing the stack trace of a method call.
-Xtrace:trigger=method{java/lang/Throwable.<init>,jstacktrace,sleep},print=mt,sleeptime=500,stackdepth=5This OpenJ9 Xtrace configuration sets a trigger that fires whenever the constructor java/lang/Throwable.<init> is called. When triggered, it will:
- Output a mini-trace (
print=mt) - Capture a short stack trace up to 5 frames (
stackdepth=5) - Optionally sleep 500 ms (
sleeptime=500) to slow execution so repeated triggers are easier to observe.
We can observe dozens of ClassNotFoundException, NoSuchMethodException and NoSuchFieldException. These errors are often caused by missing classes, library version mismatches, JAR conflicts, or serialization issues across driver and executor nodes, largely because Spark relies heavily on Java reflection, dynamic classloading, and user-provided JARs.
Hmm … sounds like the perfect topic for another article! 🤔
Anyway, if we are patient — waiting several minutes, or by disabling the sleep setting and generating a large trace file — we eventually hit the EOFException errors.
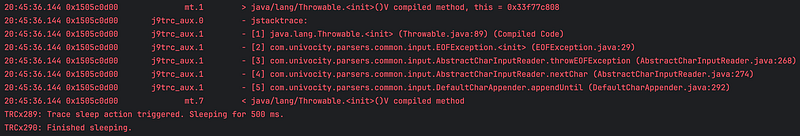
First the stack trace is generated, and then the sleep is applied.
🔥 Lava Lab — Xdump
If IBM Semeru is a volcano, -Xdump is the early-warning system built into its core. It doesn’t wait for a catastrophe to strike blindly; it senses tremors—low memory, crashes, signals, or unhandled exceptions—automatically capturing the JVM’s innards. Heap dumps, javacores, system snapshots, or even core files: whatever we need to understand the eruption, it’s ready.
The Dump Engine is like a smart first responder:
- Triggers: react to signals, errors, VM stops, or memory thresholds.
- Outputs: javacores, heap dumps, core dumps, Snap logs.
- Behavior: synchronous, asynchronous, or conditional, so it only acts when danger looms.
With -Xdump, OpenJ9 doesn’t just fail—it leaves breadcrumbs, telling us exactly why the eruption happened, without slowing down the volcano in normal times.
Running test_2.py (again)
We can use this trick to catch EOFException errors more easily:
-Xdump:heap:events=throw,filter=com/*,opts=SYSTHROWThis tells OpenJ9 to react whenever an exception is thrown in the com package, with SYSTHROW capturing detailed system-level information. The neat part: we can configure it to print or log the exceptions without actually generating full heap dumps, giving us real-time visibility into problematic objects without the performance cost of large dumps.

-Xdump can show us every exception that gets thrown.
Running test_3.py
In Stranded On Dates Rows, we saw that Spark’s built-in to_date used to throw a java.text.ParseException internally whenever a column contained an invalid date string—even empty strings triggered these hidden errors.
In Spark 4, java.text.ParseException errors have been replaced by java.time.format.DateTimeParseException, and date parsing is now ANSI SQL–compliant by default. This means that attempting to parse an invalid date string will throw an exception that is propagated immediately, totally stopping the execution.
To restore the previous behavior, ANSI must be disabled:
"spark.sql.ansi.enabled" = "false"With ANSI off, running the test produces a strange result:
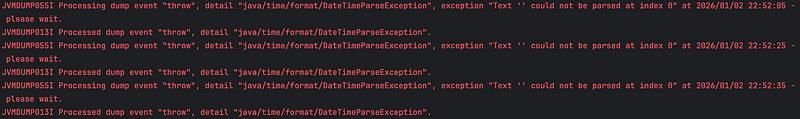
Three DateTimeParseException traces appear.
Why only a few? And why exactly three?
In reality, only one DateTimeParseException object is created. The JVM prints a trace every time the exception is thrown, even if it is immediately caught. So three printed traces simply mean the same exception was thrown (propagated) three times.
In Spark 4, the date/time parser was rewritten. For performance and safety, it throws a single DateTimeParseException per task/codepath for repeated invalid values. This change avoids the massive overhead Spark 3 incurred by creating thousands or millions of exception objects.
If we generate multiple different invalid date strings, we do see multiple exceptions. The helpful part is that each exception message includes the offending value, so the traces now give us insight into what is wrong with the data — we’re no longer blind.

Multiple invalid date strings ➜ multiple exceptions thrown.
🔥 Lava Lab — verbose:gc
If IBM Semeru is a volcano, -verbose:gc is the seismograph bolted directly to the caldera—steadily ticking, barely audible, but packed with every tremor, shift, and pressure change deep inside the memory magma. It doesn’t interfere with the eruption; it simply listens. Every allocation quake, every collection tremor, every compaction ripple—captured in a clean, continuous heartbeat of the heap.
What it tells us:
- Nursery quakes: Minor GCs, scavenges, allocation rates.
- Tenured eruptions: Major cycles, sweeps, global collections.
- Pressure shifts: When the heap is expanding, contracting, or nearing its limits.
- Timelines & pauses: Precise durations, before/after sizes, object movements.
And OpenJ9 enhances the classic HotSpot-style logs with metronome timing, cycle IDs, and event sequencing — turning GC logs into a structured chronicle instead of a firehose of text.
The GC Log Engine works like a calm, methodical volcanologist observing the mountain:
- Continuous monitoring: No triggers — just a steady capture of every memory event.
- Low noise, high insight: Lightweight enough for production, rich enough for forensics.
- Structured storytelling: Each cycle is a chapter, with timestamps, phases, and results.
- Optional deep dives: Add
-Xtrace:print={j9mm*}to pair GC logs with internal memory events for lava-scanner-level detail.
Running test_4.py (Settings #1 — No tuning)
The script creates two large Spark DataFrames with random join keys, performs a shuffle-heavy join, then a groupBy aggregation, and finally triggers execution with a no-op write.
Execution fails with a java.lang.OutOfMemoryError after the JVM is trapped in aggressive GC cycles. A 16.78 MB allocation from an executor thread could not be satisfied. Despite repeated global collections moving 881 MB of data, the Small Object Area (SOA) in the Tenure region — the space for long-lived objects — remained full. With the heap at its maximum and 0% free, the JVM could not allocate the requested memory.
Running test_4.py (Settings #2 — Increasing max memory)
Increasing spark.driver.memory from 1 GB to 2 GB prevents the job from failing, but it still takes a long time to finish. Can we do better?
The reason the Spark join takes 6+ minutes is JVM thrashing: most CPU time is spent in garbage collection instead of processing data. With over 11,700 Minor GCs, threads constantly pause to clear a tiny Nursery (Young Generation)— holds newly created objects. Because the heap starts at 8 MB (-Xms) but can grow to 2 GB (-Xmx), each shuffle block from our 200 partitions triggers a pause to expand the heap or clean the Young Gen.
Running test_4.py (Settings #3 — Increasing partitions)
What if we increase the number of partitions to make them more manageable?
This is actually counterproductive. Each new partition adds internal Spark objects and serialization buffers, flooding the already tiny Nursery with short-lived objects. GC frequency skyrockets, turning thousands of micro-pauses into near-constant interruptions, while CPU cycles are wasted on memory management instead of data processing.
Increasing partitions from 200 to 800 pushed Minor GCs from ~11,700 to over 12,000, confirming the “allocation chatter” problem. With -Xms still 8 MB, the JVM repeatedly expands the heap and pauses, stalling the job.
Running test_4.py (Settings #4 — Increasing initial memory)
By reverting to 200 partitions and setting the initial heap size (-Xms2g), we successfully stabilized the heap and eliminated the “resizing tax” that hampered previous runs. With a fixed 2 GB heap, the JVM no longer pauses Spark threads to recalculate memory boundaries, improving predictability.
However, the trace still shows over 11,700 scavenges because the Nursery (512 MB) remains too small for 200 partitions. It fills up almost immediately as shuffle data flows in, causing frequent micro-pauses. While the resizing “thrashing” has been eliminated, we still see significant “allocation chatter,” where the CPU is interrupted repeatedly to clear the young generation.
Running test_4.py (Settings #5— Decreasing partitions)
By reducing the shuffle partitions to 100 while keeping the 2GB fixed heap, we have achieved a slight stabilization, but the overall GC behavior remains almost unchanged.
Our latest trace shows 11,732 scavenges, which is nearly identical to the 11,753 seen with 200 partitions. This confirms that while we’ve halved the metadata and task overhead, the “velocity” of our actual data processing is so high that it still saturates the 512MB Nursery at the same rate.
Essentially, whether the data is split into 100 or 200 pieces, the total volume flowing through the JVM is identical, and our Nursery remains the primary bottleneck.
Running test_4.py (Settings #6— Increasing Nursery)
By doubling the Nursery size, we halved the GC frequency, dropping the total time the CPU spent paused by approximately 42% (from 6.1s to 3.5s).
While the average pause time increased slightly (from 0.52ms to 0.61ms) because there is more memory to scan per cycle, the reduction in Stop-the-World interruptions allows the Spark 4 engine to maintain a much higher instruction throughput.
This configuration effectively balances the object creation rate of our join with the JVM’s ability to clear it, transforming thousands of tiny “stutters” into fewer, more efficient collection cycles.
🔥 Lava Lab — Xtgc
If -verbose:gc is the seismograph of IBM Semeru, -Xtgc is the geothermal imaging drone—flying straight into the caldera to deliver high-resolution heat maps of the GC engine itself. Where -verbose:gc gives us the story, -Xtgc gives us the diagnostic autopsy: every phase, every subphase, every internal counter the GC normally keeps to itself.
It’s not just “GC happened.” It’s how, why, how long, which subcomponent blinked first, and what the collector was thinking.
-Xtgc exposes the inner workings of OpenJ9’s memory machinery:
- Phase breakdowns: Mark, sweep, compact, relocate — timed and annotated.
- Heap cartography: Region usage, fragmentation hot spots, age group transitions.
- GC insider stats: Work packet counts, remembered set processing, card cleaning.
- Parallelism insights: Thread participation, load balancing, work stealing behavior.
The Xtgc Engine behaves like an elite geological survey team:
- Forensic detail: Every GC cycle is dissected into millisecond-level anatomy.
- Targeted activation: Usually enabled only when diagnosing odd behavior or tuning memory strategies.
- Synergy with other tools: Combine with
-Xtraceonj9mm*for a full memory subsystem MRI. - Still lightweight — but not silent: More overhead than
-verbose:gc, but still engineered for safe, temporary use in production emergencies.
Running test_4.py (Settings #7— Enabling GC allocation tracing)
Replacing -verbose:gc with -Xtgc:allocation reveals that the bottleneck isn’t just the frequency of GCs, but extreme Thread Local Heap (TLH) churn. HotSpot JVM calls them TLABs (Thread Local Allocation Buffer), but it serves the same purpose: achunk of the young generation (eden) reserved for a single thread to allow fast, lock-free object allocation.
Even with a 1GB Nursery, each Spark thread is exhausting its local allocation buffer over 7,000 times during the join, creating a high-frequency synchronization tax. This “TLH chatter” explains why the execution remains at 5.6 minutes: the CPU is constantly interrupted by memory management requests at the thread level.
Running test_4.py (Settings #8— Enabling Spark offHeap memory)
The inclusion of offHeap memory is clearly working as intended. By moving the shuffle and execution data out of the Java heap, we’ve reduced the “velocity” of objects hitting the JVM Nursery. Each thread now has a less crowded “on-heap” environment to work with, allowing it to complete more work before needing to refresh its allocation buffer.
🕳️ Off-Heap Memory: Escaping the JVM Volcano
While we’re at it, let’s take a closer look at this Spark feature.
In Apache Spark, data typically lives in the JVM heap — a crowded, volatile crater where objects churn, fragment, and eventually trigger Garbage Collection (GC) eruptions. When shuffle-heavy workloads or massive DataFrames flood this crater, the JVM “overheats,” causing long Stop-the-World pauses that freeze our application.
Off-heap memory is Spark’s strategic escape tunnel. It moves data out of the JVM’s jurisdiction into native memory, keeping the “lava” of GC at bay.
What Off-Heap Memory Actually Is
Off-heap memory is a native memory region managed directly by Spark (via Tungsten and Netty), not by the JVM. Unlike heap memory, the Garbage Collector never visits this area.
We can enable it with:
spark.memory.offHeap.enabled = true
spark.memory.offHeap.size = 4g
By moving shuffle buffers, hash maps, and join structures into this zone, Spark stores data as compact binary rows instead of bloated Java objects.
The Result:
No Java objects ➜ No GC scanning ➜ Fewer volcanic eruptions.
⚖️ The Trade-Off: Benefits vs. Risks
On-Heap (“Volcano”)
- Management: Automated by the JVM’s Garbage Collector.
- GC Pressure: High, due to heavy object overhead.
- Data Format: Java objects, which are relatively bloated.
- Failure Mode: Can hit GC overhead limits, leading to long pauses or crashes.
Off-Heap (“Tunnel”)
- Management: Manually managed by Spark via Tungsten and Netty.
- GC Pressure: Minimal, since GC ignores off-heap memory.
- Data Format: Compact raw binary, more memory-efficient.
- Failure Mode: Can run out of direct buffer memory (OOM), often “invisibly” to the JVM.
👍 The Pros of Off-Heap Memory
Off-heap memory shines when GC overhead is your bottleneck. Because off-heap buffers aren’t part of the JVM object graph, the garbage collector spends far less time “walking the tree,” leading to dramatically shorter GC pauses. Spark’s Tungsten engine further accelerates execution: off-heap data is stored in a C-style, cache-friendly memory layout that boosts CPU-bound SQL operations like joins, aggregations, and filters.
Native memory also offers predictability. Unlike the heap, which can fragment under heavy workloads, off-heap memory remains compact and steady. This consistency pays off during massive sorts or large-scale joins, where traditional GC cycles would otherwise slow things to a crawl.
👎 The Cons of Off-Heap Memory
Off-heap memory isn’t without risks. Because the JVM cannot see it, we may think our executor is safe with 50% heap usage — only to have the OS terminate the process for exceeding container limits. Debugging is also trickier. Standard heap dumps won’t reveal off-heap structures; we need Native Memory Tracking (NMT) or tools like /proc/<pid>/smaps to peek beneath the lava.
Finally, off-heap memory requires careful planning. We must account for spark.executor.memoryOverhead when sizing our containers. If the sum of heap, off-heap, and overhead exceeds our container’s limit, YARN or Kubernetes may kill our pod without warning.
🐱 Schrödinger’s Paradox
In systems engineering, observation is never innocent. Turn on logging, tracing, or profiling, and the system shifts under our feet — bottlenecks move, timings distort and the very act of watching changes the outcome. That’s the essence of Schrödinger’s Paradox applied to debugging: the moment we measure, we interfere.
But Semeru’s OpenJ9 bends that rule. Its built-in diagnostic arsenal — -Xtrace, -Xdump, -verbose:gc, -Xtgc — runs inside the heart of the JVM with almost no footprint. We get deep insight into memory, threads, GC, and system behavior while leaving performance nearly untouched. It’s quantum-style visibility without collapsing the experiment.
So as we enter 2026, I wish you all an interesting year of debugging and discovering, with cleaner traces, lighter diagnostics, and the thrill of uncovering strange new issues without disturbing the volcano you’re studying.
🙏 Greetings & Thanks
This article would be incomplete if I didn’t take a moment to greet and thank everyone I shared 13 years at LDA with. Thirteen years might sound a bit like a curse, but I entered as a Level 1 farmer and left as a Level 25 wizard in terms of performance and troubleshooting. 🧙
This article is dedicated to the Architecture Department(especially Jose and David M.) and to everyone who has been part of the team managing the legendary IBM WebSphere Application Server (especially Javi, Pablo, Julio, Manu, Jose, Andrés and, of course, Perdiguero).
“An empty shell was all I’d see,
With a shadow of that stack trace hanging over me.
A bustedmain()whose cause I didn’t know,
But with Semeru’s traces on, everything is clear now.”
(adapted from “Beggin’” by Måneskin)