
Apache Spark WTF??? — I Like It When A Plan Comes Together (Part I)
When I was a kid, I was a fan of TV shows like the A-Team. No matter how crazy their situations got, their plans always came together —…
“They try to make me use checkpoints But I said: No, no, no Yes, my job lasts, and finally cracks, when Spark increases the plan But still: No, no, no” (adapted from “Rehab” by Amy Winehouse)
The Case
Our story begins a few weeks ago when an email landed in my inbox with the dreaded word: OutOfMemoryError. The moment I saw that, a surge of excitement and curiosity kicked in — nothing grabs my attention faster.
The issue was outlined in this gist. In short, a seemingly simple unit test from the GraphFrames test suite was blowing up spectacularly, even with 32GB of memory allocated to the Spark driver.
After some deep debugging, I discovered that GraphFrames itself wasn’t to blame — Spark was. The culprit? A single call to the connectedComponents function. This function finds weakly connected components in a graph by iteratively propagating the smallest vertex ID until all nodes in a component share the same ID. Each iteration updates vertex labels based on their neighbors, continuing until convergence.
If the previous explanation left you scratching your head, don’t worry — the key takeaway is that this process is iterative and heavily relies on caching DataFrames to avoid redundant computations. In fact, it might cache more often than usual. But here’s the catch: the method also keeps track of cached DataFrames and unpersists them as soon as they’re no longer needed.
So … where’s the problem? Shouldn’t Spark handle a relatively simple execution plan with ease? 🤔
The newly chosen logo for GraphFrames API.
DIY (=Do It Yourself)
Test #1: Making it fail
One of my go-to strategies when tackling issues like this is to follow the KISS principle— keep it simple. That means trying to reproduce the problem in a minimal test case. Since we’ve ruled out GraphFrames as the culprit, let’s remove it from the equation entirely. The real question is: Can we make Spark exhibit the same behavior and throw a similar OutOfMemoryError (OOM) just by iteratively caching a simple DataFrame multiple times? Yes, of course we can.
import org.apache.spark.sql.SparkSession
import org.apache.spark.sql.functions._

object Test1 {

  def main(args: Array[String]): Unit = {
    // Create SparkSession
    val spark = SparkSession.builder()
      .master("local[*]")
      .getOrCreate()

    import spark.implicits._

    // Create an empty DataFrame with an initial schema
    var df = spark.emptyDataFrame
    println("Initial empty DataFrame created.")

    // Start measuring execution time
    val startTime = System.currentTimeMillis()

    // Loop to modify DataFrame
    for (i <- 1 to 25) {
      // Add a new column with null values
      df = df.withColumn(s"col$i", lit(null))

      // Filter the DataFrame
      df = df.filter($"col$i".isNotNull)

      // Explain the query plan
      df.explain()

      // Show the DataFrame
      df.show()
    }

    // Print execution time
    val totalTime = System.currentTimeMillis() - startTime
    println(s"Total execution time: $totalTime ms")

    // Stop the SparkSession
    spark.stop()
    println("SparkSession stopped.")
  }
}
This code creates an empty DataFrame and iteratively modifies it 25 times. In each iteration, it adds a new column with null values, applies a filter to remove rows where the new column is null, and then prints the query execution plan and the DataFrame. Simple, right?
If we run this code, it executes smoothly with Spark completing the task in no time. But hold on, there’s a crucial piece missing: DataFrame caching. When we cache the DataFrame after the new column is added … WTF??? Not only does the query plan grow massively with each iteration, but the time and memory Spark consumes also skyrockets, spiraling out of control until it eventually throws the dreaded OutOfMemoryError.
Test #2: Making it work by brute force (the 💩ty way)
I’ve been working with Spark for over 8 years, across various projects and clients, and I’ve encountered all sorts of teams and individuals. Many of them just want their Spark jobs to run on time and without errors. So, when they find that checkpointing their problematic DataFrame solves the issue, they go with it without hesitation. The question now is: Will checkpointing our DataFrame fix it this time too?
    // Set the Checkpoint directory
    spark.sparkContext.setCheckpointDir("checkpoints")

    ...

    // Loop to modify DataFrame
    for (i <- 1 to 25) {
      ...

      // Checkpoint the DataFrame
      df = df.checkpoint()

      ...
    }
Adding only these two lines does fix our problem! Mission accomplished! End of the article! 😆 Errr … really? 🤔Why does checkpointing solve the problem?
I like to think of checkpoints in Spark as hitting the ‘save’ button in a video game — except instead of saving our game progress, we’re saving the state of our data operation. When something goes wrong (like a crash or error), it doesn’t have to start from scratch — Spark just picks up from where it left off, like respawning at the last checkpoint. It’s like … Spark can fail, but it doesn’t have to fail hard!
Internally, Spark performs checkpoints by saving the state of an RDD or DataFrame to a distributed storage system (like HDFS or a local disk) at a specified point during execution. This process involves writing the data to disk in its raw form, without compression or columnar formats like ORC or Parquet, while also updating the lineage to break computational dependencies. If a failure occurs, Spark can recover the data without re-executing the entire job.
Benefits of checkpoints:
- Fault tolerance: Enables recovery from failures without re-running the entire job, saving time and resources.
- Performance optimization: Breaks long chains of dependencies, preventing re-computation of previous stages in iterative algorithms.
Drawbacks of checkpoints:
- Storage overhead: Requires additional disk space to store the checkpointed data, which can be significant for large datasets.
- Slower execution: Writing data to disk can introduce performance bottlenecks, especially in frequent checkpointing.
Use cases:
- Checkpoints are typically used for long-running jobs — like streaming apps — or when dealing with fault tolerance in iterative algorithms.
Okay, we’re dealing with iterative algorithms, that’s true, but… are we using checkpoints for fault tolerance, or is it just because we haven’t figured out a better way to make it work?
And what happens with the checkpoint folders that Spark creates? Spark doesn’t perform any housekeeping on these checkpoint directories, meaning it doesn’t automatically clean up old checkpoint folders after an execution.
Every time Spark runs a job with checkpointing, it creates a new folder (typically within the specified checkpoint directory) to store the checkpointed data. However, once the job is done, Spark doesn’t delete or manage these folders. As a result, over time, these directories can accumulate and consume significant storage, especially if the job runs frequently or with large datasets. This behavior can lead to storage bloat unless you manually clean up old checkpoint folders, as Spark does not track or remove them once the job completes.
Test #3: Making it work also by brute force (another💩ty way)
So, why instead of relying on checkpoint mechanism we explicitly save and load the DataFrame? Could that also work?
      // Checkpoint the DataFrame
      val path = "save/df"
      df.write.mode(SaveMode.Overwrite).save(path)
      df = spark.read.load(path)
If we introduce those 3 lines between the filter and the explain … it throws the following error:
[UNSUPPORTED_DATA_TYPE_FOR_DATASOURCE] The Parquet datasource doesn’t support the column
col1of the type “VOID”.
As mentioned earlier, when we checkpoint a DataFrame, Spark stores it in raw form, meaning no type checks are performed. However, when attempting to write the DataFrame in formats like Parquet, Spark may perform type checks. Since no explicit data type is set when creating the new column, Spark struggles to infer the type correctly and fails. To prevent this, we need to explicitly cast the nullvalue to String.
df = df.withColumn(s"col$i", lit(null).cast(DataTypes.StringType)).cache()Now, our test runs without errors, but it takes Spark more effort and takes over twice the time. Why is that?
Checkpointing is faster than writing and reading DataFrames because it skips the expensive serialization, transformation, and compression required for formats like Parquet or ORC. Unlike writing and reading, which triggers Adaptive Query Execution (AQE) and introduces extra computation and I/O overhead, checkpointing directly saves the DataFrame’s state without any optimization or query planning, making it a more efficient operation.
That said, I’ve never really been a fan of checkpoints and have barely used them — except, of course, when streaming demands it. I’ve always preferred writing and reading DataFrames since they keep the data in a much friendlier format for later auditing or querying, making my life way easier when dealing with intermediate steps in my applications. Plus, thanks to the overwrite mode, the data store stays clean and predictable — no tedious housekeeping required.
But let’s be real — having to write intermediate data just to nudge Spark into handling its execution plans properly? That feels like a bit of a hack, doesn’t it? Surely there’s a cleaner way to deal with this… right?
Test #4: Making it work by KISSing the enemy (a 😘 way)
If we inspect the plans of our first test, before and after caching the DataFrame, one thing stands out: caching the DataFrame triggers AQE. When no caching is applied, the plan doesn’t mention AQE, but once caching is added, it appears.
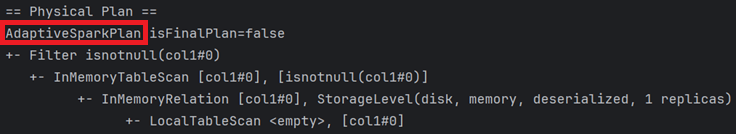
AQE kicks in after caching.
Caching the DataFrame triggers AQE because it forces Spark to materialize the data, prompting it to optimize the query plan based on how the data is stored and partitioned. This allows AQE to adjust execution strategies like partitioning or shuffle operations. Without caching, Spark doesn’t need to materialize the data upfront, so AQE isn’t triggered since it’s only considering the transformations rather than how the data will be used or stored.
Could we fix it by just disabling AQE and keeping our Spark plan simpler? YES!!!
    val spark = SparkSession.builder()
      .master("local[*]")
      .config("spark.sql.adaptive.enabled", "false")
      .getOrCreate()
Even though the plan grows with each iteration, Spark seems to handle it well. No OOM error is thrown, and the test completes in just a few seconds.
NOTE: In the case of the GraphFrames unit test, the issue was also resolved by disabling AQE.
Test #5: Making it work by outwitting the enemy (the💡way)
Oh mighty Lords of Distributed Computing, Masters of Executors and Keepers of Partitions, Isn’t there any way to prevent Spark from making the plan larger?
Yes, indeed there is … Instead of caching the DataFrame after withColumn, we just need to cache the DataFrame after the filter. That’s it. Plain and simple.
      // Add a new column with null values
      df = df.withColumn(s"col$i", lit(null))

      // Filter the DataFrame
      df = df.filter($"col$i".isNotNull).cache()
But … WHY?
When we cache a DataFrame after a withColumn operation, Spark has to track the transformations and dependencies added to the plan, even if there are no rows. Since withColumn involves creating new columns and adding them to the schema, it introduces more complexity in the logical plan. This leads to Spark keeping a larger, more detailed plan to account for these added transformations.
On the other hand, when we cache the DataFrame after a filter, Spark only needs to track the filtering operation, which is less complex. Even without rows, the filter operation is a simpler transformation, resulting in a more compact plan.
So, by caching after filtering, we’re effectively breaking the lineage at a more optimal point, preventing Spark from carrying over the entire transformation history.
To Be Continued … (aka Final Thoughts)
Flabbergasted? You should be! If you thought this mystery was wrapping up… think again! Buckle up, because this is just the first installment of a thrilling three-part series about Spark plans that don’t always come together as expected.
In the next episode, we’ll dive into the GraphFrames issue and try to uncover what’s really going on. Then, in the grand finale, we’ll dig even deeper into Spark’s little dirty secrets with plans — and, more importantly, how to tame it once and for all… if that’s even possible!
As always, you can find the repository for this article here.
A Word of Caution for Spark 4 Users
At the time of writing, the first version of Spark 4 is just around the corner. If you try running our first test in this version, you’ll notice something strange — no OutOfMemoryError, no delay, no drama. What’s going on?
Well, in Spark 4, Adaptive Query Execution is skipped by default if the query has no exchanges or subqueries. Since our test only adds columns and filters rows, AQE doesn’t kick in, and Spark behaves as if AQE were disabled.
Want to reproduce the issue in Spark 4? You’ll need to force Spark to apply AQE to your queries:
.config("spark.sql.adaptive.forceApply","true")“I ain’t got the time And if the project manager thinks it’s fine He’s trying to make me use checkpoints But I won’t nod, nod, nod” (adapted from “Rehab” by Amy Winehouse)
Sick and tired of debugging some error or performance issue? I might help you! Make my day and send me your case! I’m genuinely passionate about “exotic” errors and performance challenges . Don’t hesitate to reach me out at https://www.linkedin.com/in/angel-alvarez-pascua.